Service
Data Validation and Quality Assurance for AI Datasets
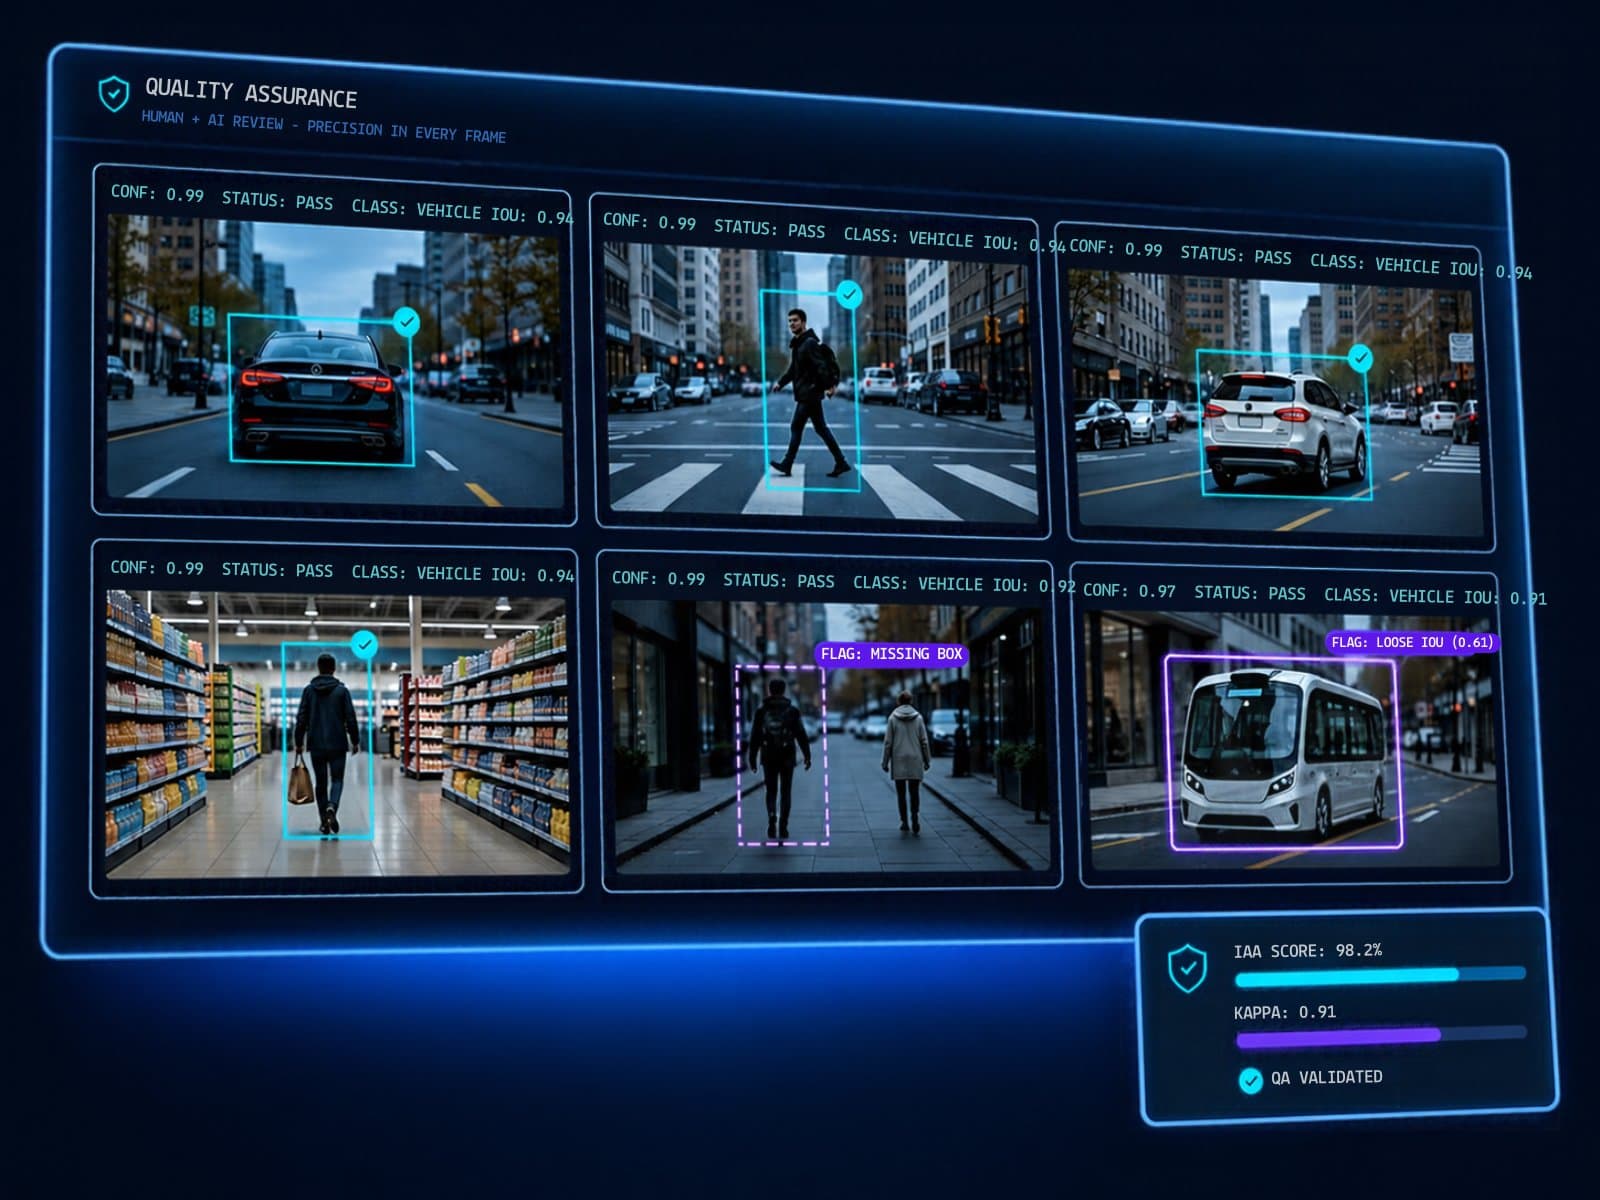
Noisy labels teach models to repeat errors at scale. We validate datasets — ours or ones you already have — with multi-pass review, agreement scoring and IoU checks, and tell you exactly what to fix.
The problem
What goes wrong without it.
Where training data usually breaks — and what this service is designed to prevent.
- Systematic annotator errors transfer directly into model behaviour; more data does not cancel them.
- Missing boxes, redundant boxes, loose geometry and wrong classes or attributes all degrade accuracy.
- Automatically generated labels — including VLM output — still need human review for hallucinations and edge cases.
Scope
What is included.
Multi-pass review
Two QA passes by default; consensus by several annotators for the hardest cases.
Inter-annotator agreement
Agreement scoring on every batch to catch unclear guidelines early.
Geometry checks
IoU validation of boxes and masks against reviewed ground truth.
Label audits
Audit of an existing dataset: error types, rates and where they cluster.
Auto-label validation
Human review of model- or VLM-generated labels before training.
Guideline fixes
Updated guidelines and re-labeling of affected samples.
What you get
- QA report: error types, rates and examples per class
- Corrected labels or a prioritized fix list
- Agreement metrics per batch and per class
- Updated annotation guidelines
Quality
Every batch goes through multi-pass QA and inter-annotator agreement scoring — our QA pass rate is 98%+, with 954+ hours of data validation delivered.
FAQ
Validation & QA questions.
Can you validate a dataset annotated by another vendor?
Yes. We audit existing labels, report error types and rates per class, and either correct them or give you a prioritized fix list.
Does more data make up for annotation errors?
Only for random errors. Systematic errors — the same mistake made consistently — are learned by the model, so they must be found and fixed.
Do you review auto-generated or VLM labels?
Yes. Automatically generated labels still need human review for hallucinations and edge cases before they are used for training.
Further reading
From the BoBox blog.
Data Quantity vs Data Quality
A smaller dataset with high data quality can provide more meaningful insights than a larger dataset with lower quality. Here's what you need to know about the data quality tradeoff.
Taskforce Oriented to Deliver Best Quality Dataset for AI Models
Who does what in a data annotation project? The roles of the ML specialist, taxonomy lead, annotators, project manager and reviewers — and how they work together to deliver a high-quality dataset.
Human Image Annotation in the Era of VLM: Why It Is Still Key
Is human annotation dead? Discover why VLMs need RLHF and Ground Truth data to prevent hallucinations and ensure Computer Vision accuracy.
Validation & QA, done right the first time.
Tell us about your data, model and timeline. A senior team member will reply within 72 hours.