Service
Image & Video Annotation Services for Computer Vision
From single images to multi-hour video streams, we label exactly what your model needs to learn — objects, tracks, actions and attributes — following a taxonomy agreed with your team before production.
The problem
What goes wrong without it.
Where training data usually breaks — and what this service is designed to prevent.
- Generic labels describe what is in a frame; your model needs what matters for the business — a missing hard hat, not just “person standing”.
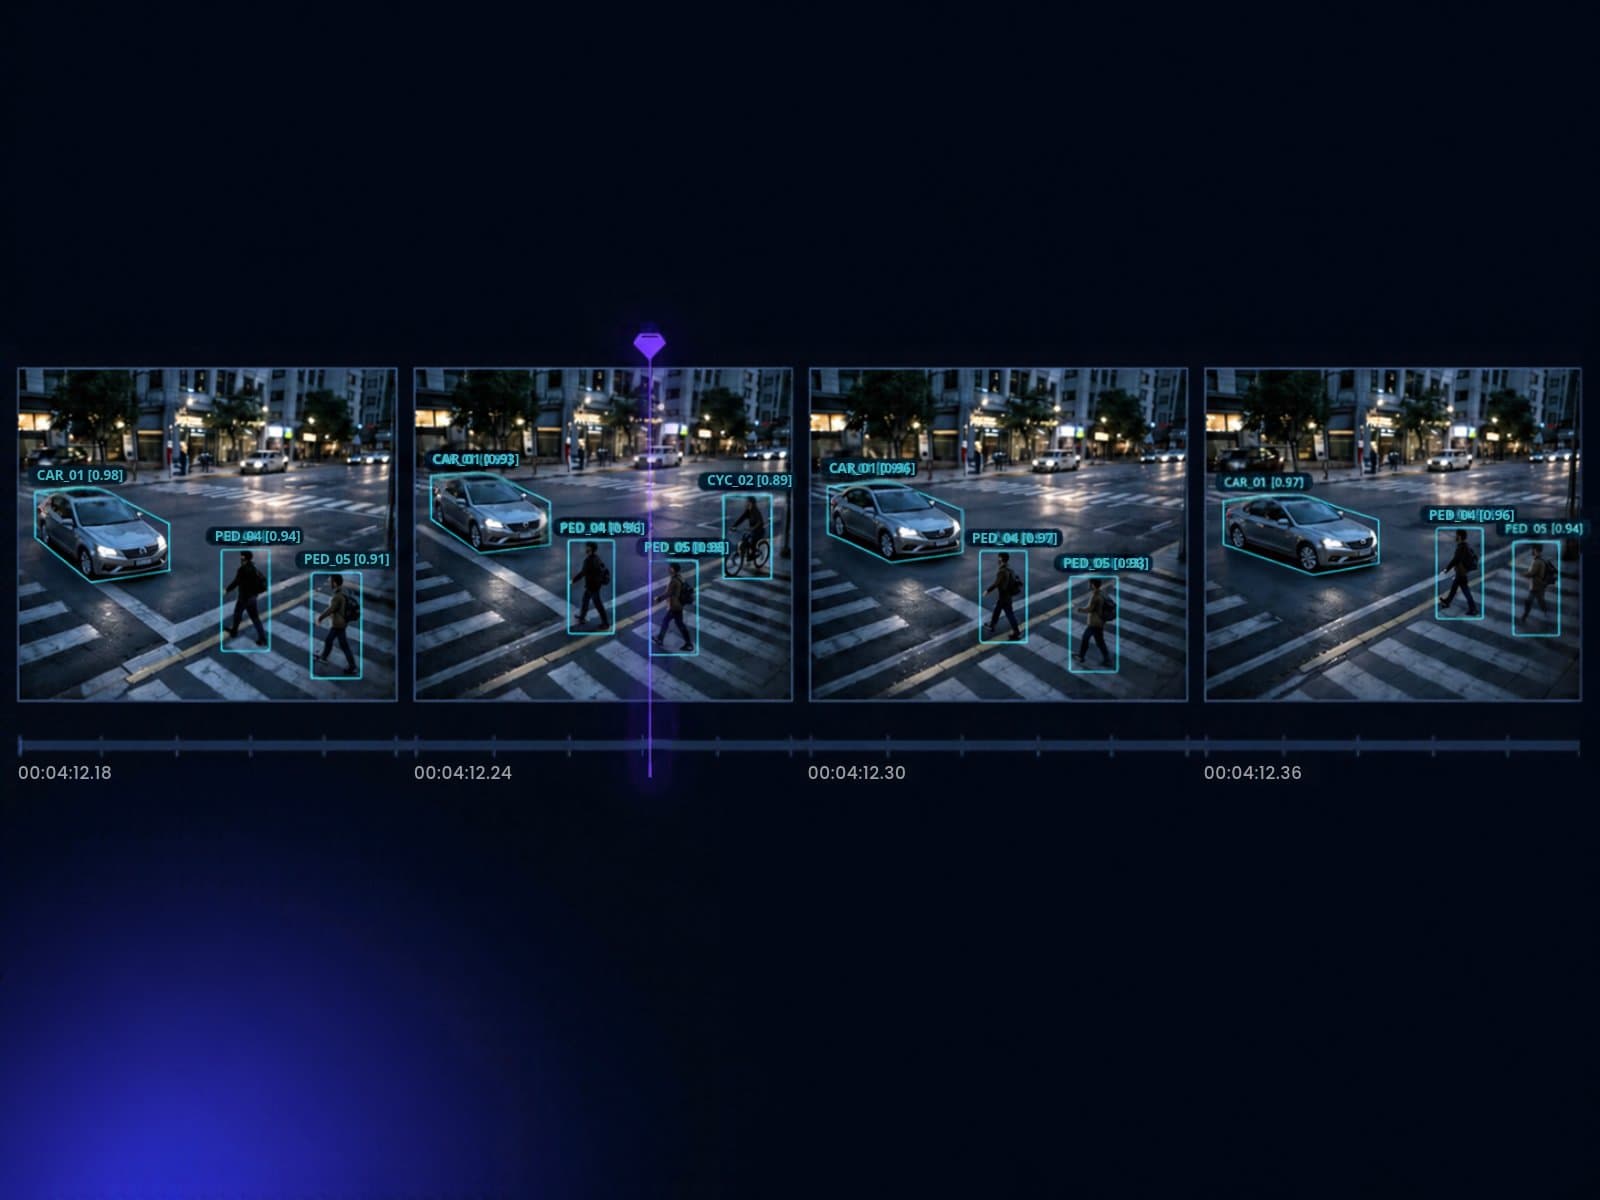
- Video multiplies inconsistency: the same object must keep its class and ID across thousands of frames.
- Rushed annotation produces inconsistent labels, which train unpredictable models and force expensive retraining.
Scope
What is included.
Object detection
Bounding boxes for every relevant object, by class, with occlusion and truncation rules.
Object tracking
Consistent track IDs across frames for people, vehicles and products.
Action & event recognition
Temporal labels for actions, events and states in video.
Classification & tagging
Image- and frame-level tags, from simple (day/night) to domain-specific.
Attributes
Per-object attributes such as colour, state, PPE worn or not.
AI-assisted pre-labeling
Auto-labeling and tracking in CVAT or SageMaker Ground Truth, then human review.
What you get
- Labeled images or frames in your format (COCO JSON, YOLO, Pascal VOC, CSV, CVAT XML)
- Written annotation guidelines and class taxonomy
- QA report after two review passes
- Edge cases flagged for your ML team
Starting prices
- 2D bounding boxCamera€0.04 / box
- Classification / tagCamera€0.03 / tag
Starting prices in EUR, net of VAT, with two QA passes included. Your final unit price depends on object density, number of classes and attributes — we confirm it after a sample.
All prices, pilot and NDAFAQ
Image & Video questions.
Do you annotate long videos?
Yes — from short clips to multi-hour streams. We agree frame sampling and tracking rules up front so IDs stay consistent across the whole video.
Do you use automatic pre-labeling?
Where it helps. We use auto-labeling and object tracking in CVAT or AWS SageMaker Ground Truth, and every pre-label is reviewed by an annotator.
Can you work in our annotation tool?
Yes. We work in CVAT or SageMaker Ground Truth by default, or in your own tool if you prefer.
Further reading
From the BoBox blog.
Why Data Annotation is Our Mission Critical?
Data annotation is a critical component of any AI project, particularly in computer vision, where precise labeling of images directly impacts model performance.
Human Image Annotation in the Era of VLM: Why It Is Still Key
Is human annotation dead? Discover why VLMs need RLHF and Ground Truth data to prevent hallucinations and ensure Computer Vision accuracy.
Computer Vision for Vehicle Detection
Vehicle detection enables counting, tracking, and behavioral analysis. From traffic management to toll systems and drive-through operations — how CV powers smart transportation infrastructure.
Image & Video, done right the first time.
Tell us about your data, model and timeline. A senior team member will reply within 72 hours.